
GLM-5.2
GLM-5.2 is the flagship model built for the long-task era, featuring a truly usable 1M context window and 128K max output tokens. With GLM-5.2, developers can complete the entire development chain from requirements to deployable artifacts in a single continuous task. GLM-5.2 keeps engineering standards reliable across extended sessions.
Feedback
freeTrialImage.bannerPity
freeTrialImage.upgradeUnlock
- ✓freeTrialImage.benefitHd
- ✓freeTrialImage.benefitWatermark
- ✓freeTrialImage.benefitUnlimited
All Tools
Discover our comprehensive AI-powered animation toolkit
MiniMax H3
MiniMax H3 AI Video Generator
Seedance 2.5
The Future of AI Video Is Here.

Seedance 2.0
The Future of AI Video Is Here.

Veo3.1
Create Stunning Videos with Veo3.1
FLUX 3 Video Generator

Kling 3.0
Next-Gen AI Video Generator
Grok Video Generator
Create Videos from Text or Images with AI
MiniMax H3 video generator
MiniMax H3 AI Video Generator
Meet GLM-5.2: A Model for Work That Runs Long
GLM-5.2 is the flagship base model shaped for the long-task era, pairing a genuine 1M lossless context with up to 128K output tokens. Its training was reinforced around long-range coding agent scenarios — large-scale implementation, automated research, and performance tuning. Engineering conventions hold steady through extended sessions, and GLM-5.2 keeps an entire project-level context inside one reasoning chain.
- A Usable 1M WindowProject-scale engineering and hours-long jobs fit comfortably inside the GLM-5.2 context window, with no silent truncation along the way.
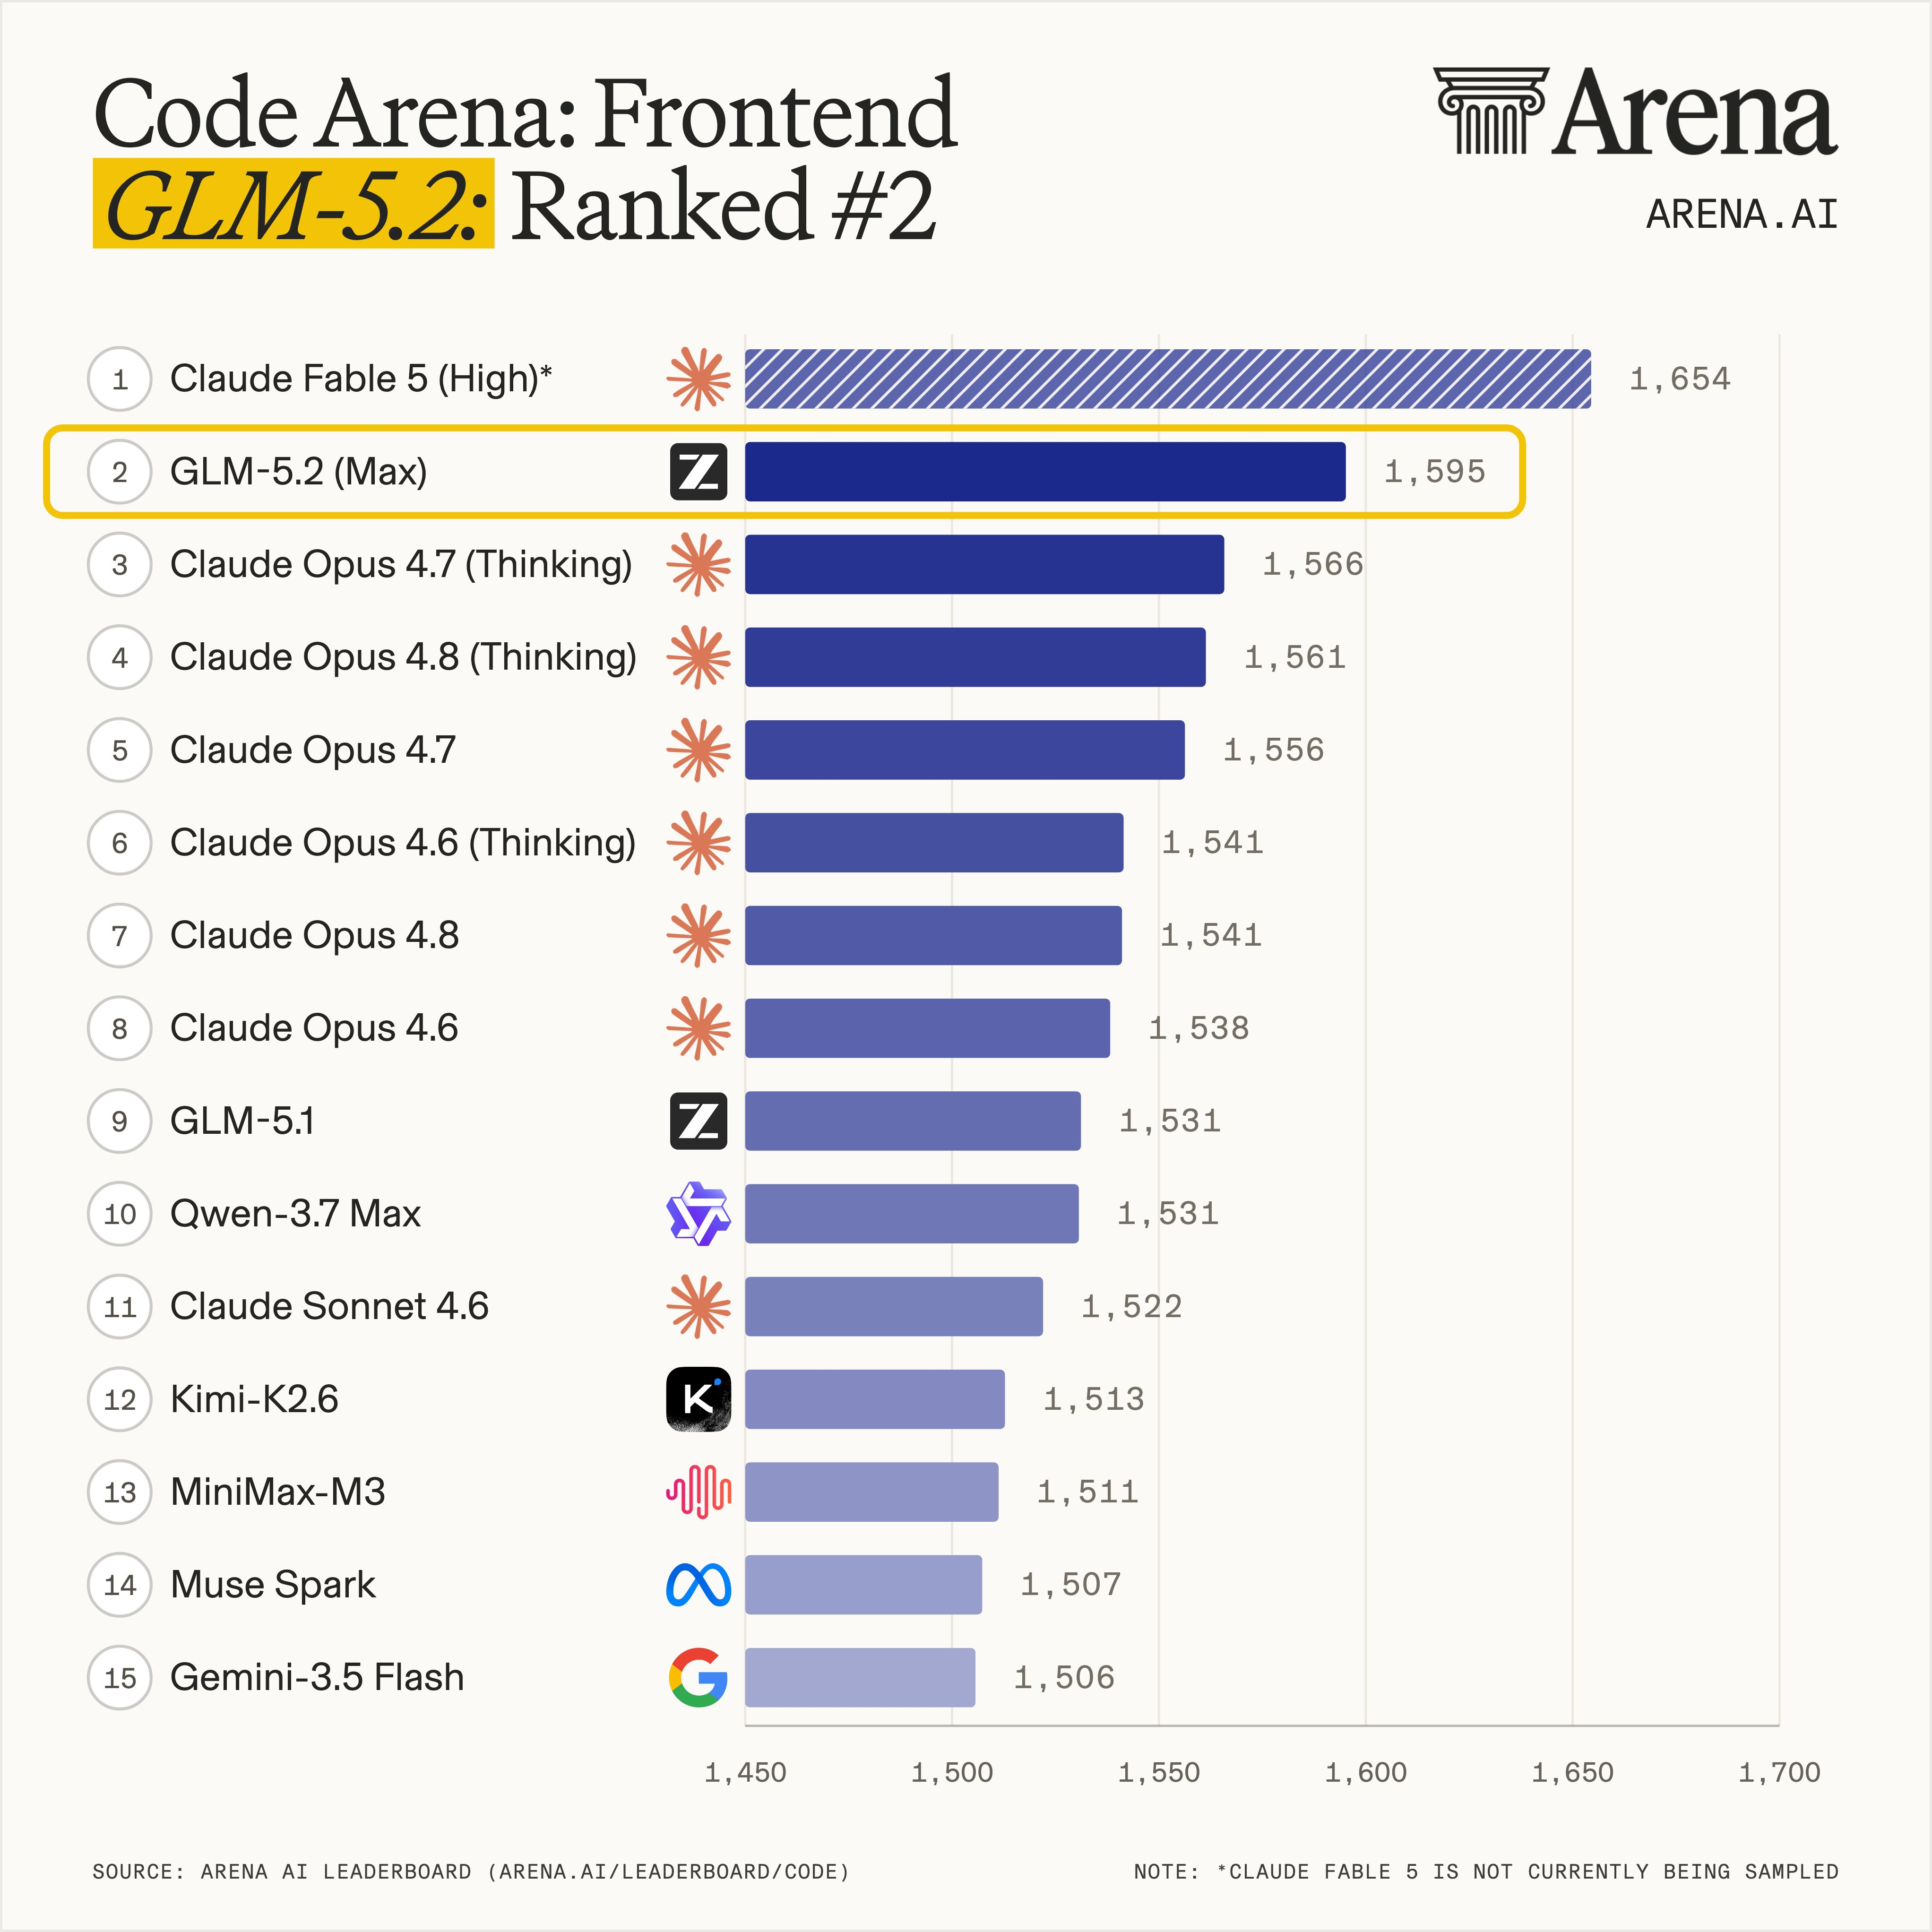
- Benchmark-Leading CodeOn mainstream coding benchmarks GLM-5.2 holds open-source SOTA, and it sits at the top of Code Arena among the models currently available.
- Production-Grade DisciplineCode style, architecture boundaries, and dependency constraints are respected the way a real production team would expect from GLM-5.2.
Running GLM-5.2 in Three Steps
Point GLM-5.2 at your project in three short moves, from endpoint setup all the way to a deployable artifact.
Capabilities Packed Into GLM-5.2
Several thinking modes, streaming responses, tool calling, context caching, structured output, and MCP integration all ship inside GLM-5.2 for end-to-end development work.
Adaptive Thinking Modes
GLM-5.2 shifts between several thinking modes, so light requests stay quick while heavy ones get deeper reasoning.
Live Streaming Responses
Tokens arrive as they are produced, which keeps interfaces built on GLM-5.2 feeling responsive rather than frozen.
Tool & Function Calling
GLM-5.2 calls external tools and services directly, wiring model output into the rest of your stack.
Smart Context Caching
Cached context trims latency on long conversations and keeps GLM-5.2 efficient across extended exchanges.
Structured Data Output
JSON and other structured formats come back clean from GLM-5.2, ready for downstream systems and data pipelines.
MCP Tool Integration
GLM-5.2 plugs into external MCP tools and data sources, widening the scenarios an application can cover.
GLM-5.2: Questions People Ask
Straight answers about GLM-5.2 — what it is, what it can build, how fast it runs, and where it fits best.
What exactly is GLM-5.2?
GLM-5.2 is a flagship base model designed for the long-task era, with a usable 1M context and up to 128K output tokens, aimed squarely at project-level engineering.
Which tasks can GLM-5.2 handle?
GLM-5.2 covers project-level engineering, long-range refactoring, real-device mobile debugging, mini-program and mini-game development, plus research replication.
How quickly does GLM-5.2 respond?
Streaming output and context caching keep GLM-5.2 moving through long-range jobs, so extended sessions stay responsive instead of stalling.
Does GLM-5.2 write good code?
GLM-5.2 holds open-source SOTA on mainstream coding benchmarks and leads Code Arena globally among available models, roughly on par with Claude Opus 4.8.
How much context can GLM-5.2 hold?
A solid 1M lossless window — enough for project-level engineering context while performance stays stable throughout.
Where does GLM-5.2 fit best?
Web development, mobile apps, WeChat mini-programs, mini-games, scientific code replication, and coding-to-video pipelines are all natural fits for GLM-5.2.
Put GLM-5.2 to Work Now
Spin up GLM-5.2 and let a genuine 1M context carry your next development project from the first prompt to a shipped build.